SvectorDB
Serverless vector database optimized for AWS environments.
Free
Framework for processing large data sets across multiple systems.
Apache Hadoop is an open-source framework designed for processing large amounts of data across many computers. It allows organizations to store and analyze vast data sets without needing expensive hardware.
The software runs on multiple machines, providing scalability for different needs. New computers can be added easily to increase capacity. Built-in reliability ensures that data processing continues smoothly, even if some machines fail.
This framework supports a variety of data formats and enables efficient large-scale data analysis. Companies can leverage it for tasks like understanding customer behavior, enhancing operational data management, and facilitating machine learning workflows.
Serverless vector database optimized for AWS environments.
Real-time data analysis for informed decision-making in engineering.
Secure and organized file storage accessible from any device.
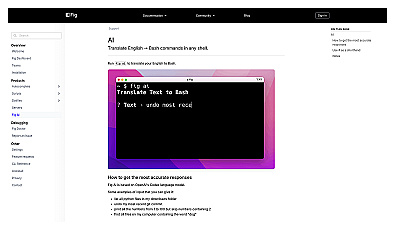
Translate plain English into Bash commands effortlessly.
Quickly convert and edit various data formats online.
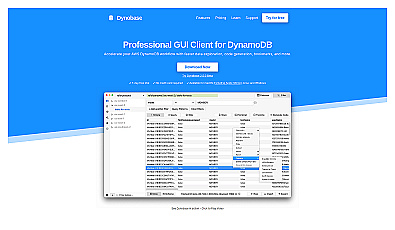
Graphical interface for managing DynamoDB data effectively.